




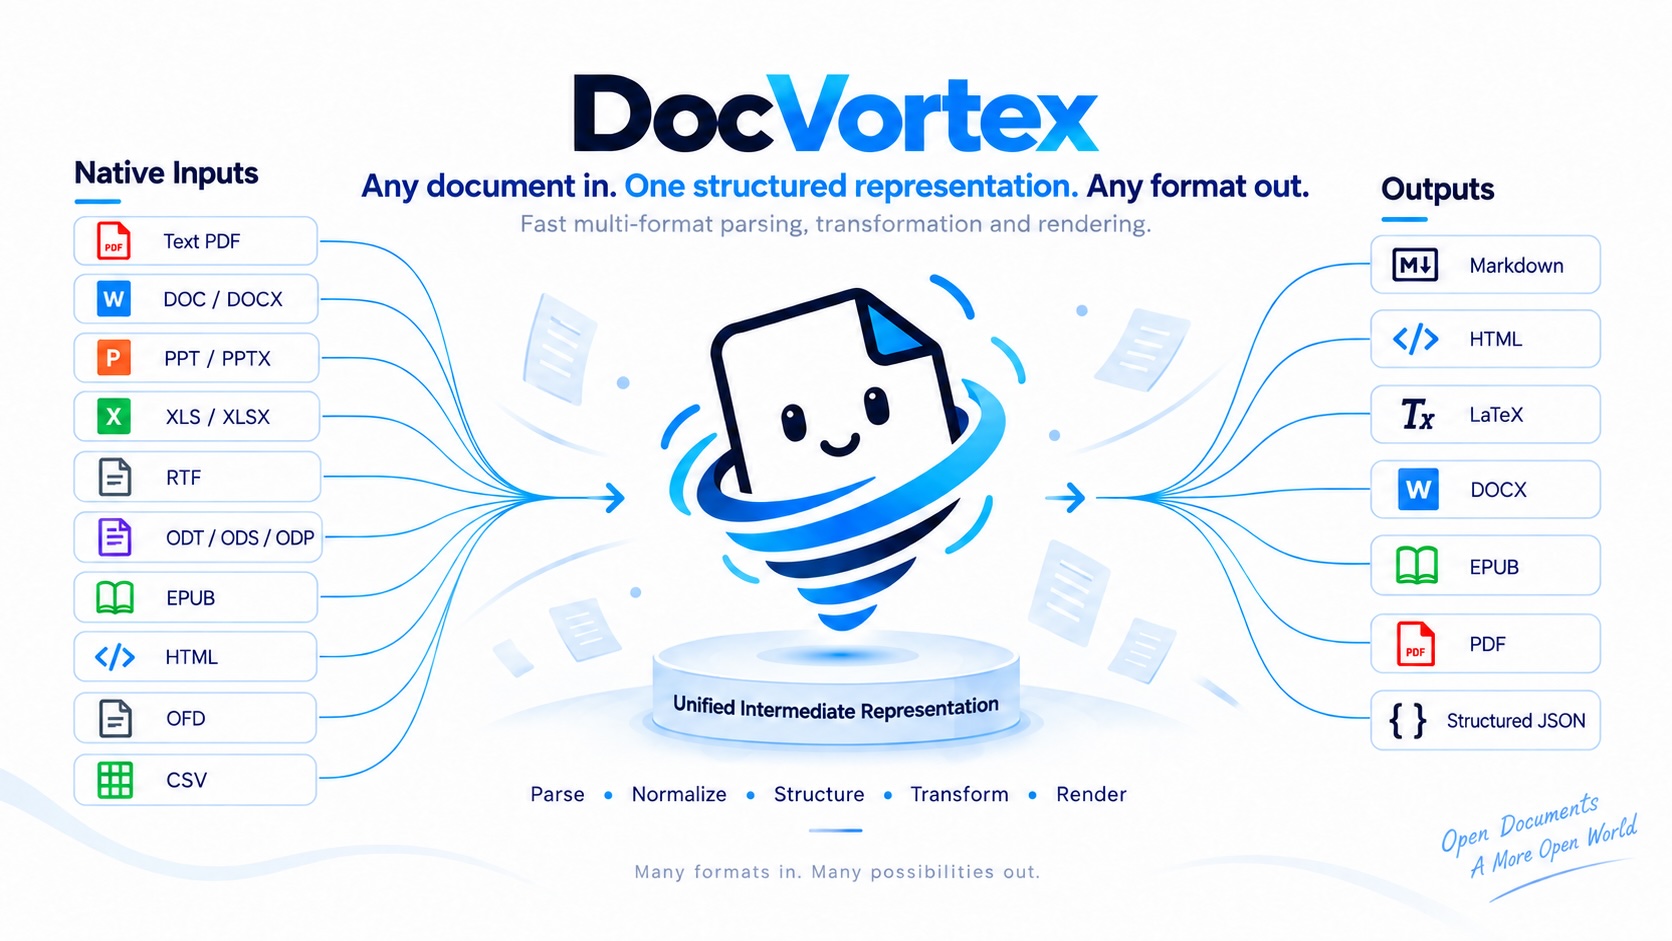
DocVortex is a standalone Python engine for parsing and converting documents. It reads native text and document structure into a unified representation, then exports the result in the formats your workflow needs.
- Multi-format input — read native-text PDFs, Office files, OpenDocument files, EPUB, HTML, OFD, CSV and TSV.
- Parse once, export many times — reuse the same result for Markdown, HTML, LaTeX, DOCX, EPUB, PDF and structured JSON.
- Portable results — save document structure and image assets in a Bundle, then export again without the source file.
- Composable APIs — use the complete pipeline or integrate analysis, postprocessing and rendering separately.
Native parsing works without an OCR or VLM inference service. Use DocVortex directly through its CLI or Python SDK.
DocVortex does not download models or perform PDF OCR. When OCR is required, it reports pdf_ocr_unsupported and asks you to download and install MinerU to process the document.
Release 0.5.10 uses Rust acceleration: public parsing is 2.93× as fast as 0.4.25 on the tested corpus.
| Pipeline | 0.4.25 python | 0.5.10 rust | Speedup | Time reduction | Peak RSS reduction |
|---|---|---|---|---|---|
DocVortex public parse() |
42.36 s | 14.48 s | 2.93× | 65.82% | 31.17% |
| MinerU Flash | 44.50 s | 14.44 s | 3.08× | 67.55% | 29.84% |
| MinerU shared PDF processing | 76.28 s | 12.85 s | 5.94× | 83.16% | 35.65% |
Same-machine warm-run comparison on 32 PDFs / 299 pages (31 PDFs for Flash). The existing 0.4.25 measurements are reused. For 0.5.10, each document is warmed once and timed five times in each of three balanced rounds; times sum the medians of the three per-document medians. RSS reductions are medians of per-document process-tree peak RSS reductions. MinerU results include improvements in both projects. The shared pipeline excludes model computation; excluding the extreme dense-table sample, its speedup is 2.87×.
Requires GIL-enabled CPython 3.11–3.14, pypdfium2 5.13.0 or newer, and ONNX Runtime 1.24.4 or newer (DirectML on Windows x64). On macOS, installation requires Apple Silicon and macOS 14 or newer; Intel Macs are no longer supported as of 0.6.0.
Version 0.6 keeps the Python SDK and CLI and requires its bundled Rust native extension.
Releases contain ABI3 wheels for Linux x86_64/aarch64 (glibc 2.28+), Windows x86_64/ARM64,
and macOS arm64. Pure Python wheels and source distributions are no longer published.
PyPy and free-threaded Python are not supported. Starting with 0.6.1, DocVortex ignores the retired
DOCVORTEX_BUILD_NATIVE and DOCVORTEX_COMPUTE_BACKEND variables, regardless of their values.
The 0.6.0 package still rejects these variables.
Existing 0.5 installations can stay on docvortex<0.6 while migrating.
pip install docvortexConvert a text PDF to Markdown:
docvortex convert report.pdf --format markdown --output output/report.mdReplace report.pdf with a local file in any supported input format.
Use --format to choose the output; run docvortex convert --help for options.
The root-level --log-level option controls loguru output and defaults to info.
It must precede the command; DOCVORTEX_LOG_LEVEL=warning can also configure it.
Parse a document once and export it twice:
import docvortex

result = docvortex.parse("report.pdf")
result.export("output/report.md", output_format="markdown")
result.export("output/report.docx", output_format="docx")
The result owns its document structure and assets, so further exports do not
reopen or reparse the source. Existing output files are protected by default;
use overwrite=True in Python or --overwrite in the CLI to replace them.
| Document family | File extensions |
|---|---|
| PDF with native text or scanned pages | .pdf |
| Word & rich text | .doc, .docx, .rtf |
| Presentations | .ppt, .pptx |
| Spreadsheets | .xls, .xlsx, .csv, .tsv |
| OpenDocument | .odt, .ods, .odp |
| E-books | .epub |
| Web documents | .html, .htm, .shtml |
| Web archives | .mhtml, .mht |
| Open Fixed-layout Document | .ofd |
| Output | --format / output_format |
|---|---|
| Markdown | markdown |
| HTML | html |
| LaTeX | latex |
| Word document | docx |
| EPUB e-book | epub |
pdf |
|
| Structured JSON | structured_content |
PPT/PPTX and XLS/XLSX are input formats only. Structured JSON is an export format; the document JSON protocol separately defines the analysis and intermediate representations.
A Bundle packages the parsed document and its image assets for reuse across processes or machines. Load it whenever you need another output format:
import docvortex

result = docvortex.parse("report.pdf")
result.save_bundle("output/report.bundle")

restored = docvortex.load_bundle("output/report.bundle")
restored.export("output/report.epub", output_format="epub")
The restored result works without the original file. See the usage guide for Bundle contents, asset handling and overwrite rules.
Need only the title, authors or other source properties?
docvortex.extract_metadata()
reads metadata without parsing the document body.
- PDF parsing:
parse_mode="auto"(default) classifies the selected PDF pages as a whole. Atxtresult uses native parsing; anocrresult raisesDocumentErrorwith codepdf_ocr_unsupportedand a MinerU download link. Useparse_mode="txt"to force native parsing without classification. The CLI equivalent is--parse-mode auto|txt|ocr; explicit modes apply only to PDF input. - PDF OCR:
parse_mode="ocr"and--parse-mode ocrare retained for compatibility and always reportpdf_ocr_unsupportedfor PDF input. Download and install MinerU for OCR. DocVortex does not install or invoke MinerU automatically. - Mixed PDFs: auto mode does not classify or switch backends per page. A selection classified as
txtkeeps native parsing even if it contains scanned pages. Use MinerU when those pages need OCR. - PDF classification:
docvortex classify report.pdfreturnstxtorocrwithout inference or networking. Metadata extraction and the low-levelPdfModel.predict()native text API also remain offline. - PDF export: PDF sources with page geometry default to block layout restoration, with selectable text and HTML-based tables; charts retain region images. Other sources and older results use semantic reflow. Use
--pdf-layout original|reflowto select explicitly; fonts, line breaks and drawing instructions are not reproduced losslessly. See PDF output layout.
| Guide | What you will find |
|---|---|
| Usage | Stage APIs, PDF pages, classification, images and Bundles |
| Agent skill | CLI and Python SDK workflows for agents; copy the entire skills/docvortex folder to reuse |
| Examples | Local samples for PDF, Office, EPUB, web documents and OFD with a runnable demo |
| Metadata | Source properties and per-format coverage |
| JSON protocol | Document schemas, extensions and protocol migration |
| HTML protocol | Semantic markers and round trips |
| Public SDK & migration | Supported integration boundaries and the 0.4 upgrade |
| Rendering ownership | DocVortex exports and MinerU-specific renderers |
See Repository architecture for directory responsibilities,
the Python/Rust boundary, and native development commands. Source builds require the
Rust toolchain pinned in rust-toolchain.toml and the platform's C/C++ linker.
From a local checkout:
uv venv
uv pip install -e ".[test,dev]"
uv run --no-project python -m pytest -q
uv run --no-project ruff check src
uv run --no-project ruff format --check src
uv build --wheel
Bug reports and contributions are welcome. When reporting a parsing issue, include a reproducible command and a sample document you can share in GitHub Issues.
DocVortex project code is released under the MIT License.